
Poor data architecture does not always break your business systems at once. More often, it creates quiet damage: inconsistent reports, duplicated records, unclear KPIs, and decisions based on numbers nobody fully trusts. When your data flows through legacy tools, manual exports, and disconnected platforms, even a simple business question can become difficult to answer. At SKM Group, we help you understand how weak data foundations affect decision-making and what you can do to rebuild trust in your analytics. Because better decisions start with better architecture.
A practical data architecture definition is simple: it is the way your company collects, stores, organizes, moves, secures, and uses data across business systems. It is not only a technical diagram. It is a business operating model.
A strong architecture tells you where data comes from, who owns it, how it changes, who can access it, and how it becomes useful in reports, applications, automation, and strategic planning. Without that structure, your company may still collect information, but it will struggle to turn it into decisions. For decision-makers, the problem is rarely “we do not have data.” The real problem is often “we do not know which data to trust.”
From a technical view, data architecture includes databases, schemas, pipelines, APIs, integration rules, transformation logic, storage layers, reporting tools, permissions, and documentation. These elements define how data behaves.
A customer record, for example, may begin in a CRM, move through an API into an ERP system, be copied into a data warehouse, and then appear in a BI dashboard. If the structure is clean, every step is controlled. If it is not, the same customer may have different IDs, names, statuses, or revenue values in each system.
Governance is what keeps this process under control. It defines ownership, naming rules, validation standards, access policies, and accountability. Without governance, technical systems become political systems. Every department defends its own version of reality.
Reliable data architectures support two types of decisions: operational and strategic.
Operational decisions happen every day. You decide how much stock to order, which client needs support, which invoice is delayed, or which campaign should be paused. Strategic decisions are bigger. You decide whether to enter a new market, modernize a platform, invest in automation, or change pricing.
Both depend on the same foundation.
If your operational data is inconsistent, your strategic conclusions will be weak. A board-level revenue forecast is only as reliable as the customer, sales, billing, and product data behind it. This is why architecture is not an IT-only topic. It is a leadership topic.
Metadata explains what data means. It defines fields, formats, business rules, ownership, refresh frequency, and context.
Poor metadata design creates hidden traps. A report may show “active customers,” but one system may define active as “logged in during the last 30 days,” while another defines it as “has an open contract.” Both definitions may be logical, but they cannot be mixed without explanation.
This is how misleading reports are born. The numbers may be technically correct, yet business interpretation may be wrong. When executives act on unclear definitions, they may cut profitable segments, overinvest in weak channels, or underestimate risk.
Modern business systems are connected through layers. Databases store transactional information. APIs move data between applications. Warehouses and lakehouses consolidate data for analytics. BI tools visualize trends and metrics.
Each layer has a role.
But when these layers are designed without a shared data architecture model, the organization loses consistency. APIs may expose incomplete fields. Warehouses may store outdated copies. BI tools may calculate metrics differently. Databases may contain duplicate entities.
The result is simple: dashboards look polished, but the logic behind them is fragile.
Legacy systems often create the deepest data problems. Older platforms may rely on outdated databases, manual exports, hardcoded business logic, and limited integration options. Over time, these systems become expensive to maintain and difficult to connect with modern analytics platforms.
That does not always mean you need to replace everything at once. At SKM Group, we often recommend a staged modernization approach. You identify the most critical data flows, stabilize them, introduce APIs, improve validation, and gradually move toward modular architecture.
This is where understanding the top benefits of legacy software modernization becomes important. Modernization is not only about performance or user experience. It is also about making your data reliable enough to support confident decisions.
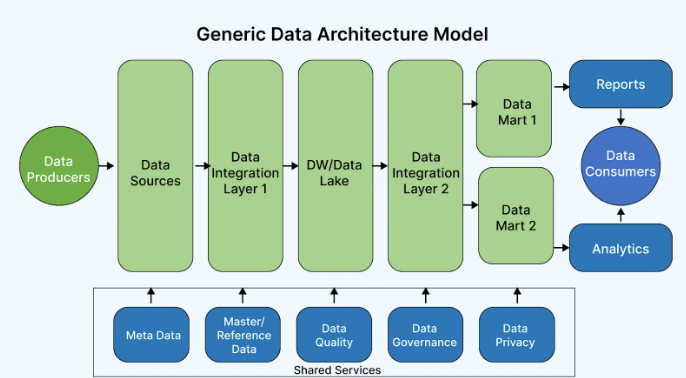
The most important data architecture fundamentals are not abstract. They are practical rules that help your company answer business questions faster and with less risk.
A reliable architecture makes data understandable, traceable, secure, and reusable. It also reduces manual work because teams no longer need to clean the same data repeatedly before every report.
Every architecture begins with sources. These may include CRM systems, ERP platforms, e-commerce tools, mobile apps, IoT devices, payment systems, marketing platforms, or internal software.
Pipelines move data from those sources into storage and analytics environments. Storage can include operational databases, warehouses, lakes, and archives. Consumption layers include dashboards, reports, machine learning models, business applications, and executive presentations.
If one layer is weak, the whole chain suffers. A dashboard cannot fix a broken pipeline. A warehouse cannot fully repair unclear source data. A machine learning model cannot compensate for missing history.
Good architecture needs clear data quality rules. These rules define what is allowed, what is rejected, and what needs review.
For example, an invoice cannot have a negative total unless it is a credit note. A customer cannot be created without a unique identifier. A product cannot be active without a valid category. These rules sound basic, but many organizations enforce them inconsistently.
Ownership matters too. If nobody owns customer data, everybody changes it. If everybody changes it, nobody trusts it.
Master data management helps your company maintain consistent definitions of core entities such as customers, suppliers, products, employees, assets, and locations.
Without it, decision-making becomes distorted. One client may appear as three different companies. One product may have several names. One supplier may be classified differently in procurement and finance.
That leads to poor segmentation, inaccurate profitability analysis, and weak forecasting.
Strong master data management gives you a cleaner view of the business. It helps you understand who your customers are, what they buy, how much they cost to serve, and where the strongest opportunities are.
Data architecture must also protect information. Access control defines who can view, edit, export, and approve data. Security rules protect sensitive information. Auditability shows what changed, when it changed, and who changed it.
This is especially important when decisions involve financial data, personal data, healthcare data, legal records, or regulated industries.
If your company cannot audit data changes, it cannot fully explain its decisions. That becomes a risk during compliance checks, investor reviews, internal investigations, and customer disputes.
Data lineage shows the path from source to report. It answers a critical question: where did this number come from?
For executive reporting, lineage is essential. A CEO, CFO, or COO should not need to guess how a metric was calculated. They should be able to trace it back to systems, transformations, rules, and responsible teams.
Traceability builds trust. It also helps teams find errors faster. Instead of arguing about numbers, they can inspect the flow.
Poor data architecture examples often look familiar because they happen in everyday business.
A retail company overorders stock because inventory data is delayed by two days. A SaaS company underestimates churn because canceled accounts remain marked as active in the billing system. A manufacturer miscalculates production costs because material prices are updated manually in spreadsheets. A financial team reports margin incorrectly because discounts are stored in a separate system and not included in the warehouse.
These are not reporting problems only. They are architecture problems.
The most common symptoms include:
Each symptom increases friction. Your teams spend more time explaining data than acting on it.
Poor data architecture design directly damages analytics accuracy. It creates missing values, duplicates, outdated records, inconsistent formats, and unclear relationships between entities.
Analytics depends on context. If your system knows that a customer bought a product but cannot connect that purchase to a campaign, region, contract, or service history, your analysis remains shallow. You see activity, but you do not understand cause and effect.
This becomes even more serious with data architecture for machine learning. Machine learning models need reliable historical data, clean labels, consistent features, and controlled pipelines. If the training data is biased, incomplete, or inconsistent, the model will produce unreliable predictions.
A weak architecture can make advanced technology look like the problem. In reality, the algorithm may be fine. The foundation is not.
This is why we often connect analytics work with broader IT services. A company does not need only a dashboard or model. It needs the technical ecosystem that makes insights dependable.
Data architecture software helps teams design, document, manage, and monitor data systems. This may include modeling tools, integration platforms, data catalogs, quality monitoring tools, observability platforms, governance systems, warehouse technologies, and BI solutions.
But software alone does not solve poor architecture.
A tool can document chaos. It can move bad data faster. It can visualize inaccurate metrics more beautifully. Real improvement comes when software supports a clear architecture, ownership model, and business goal.
At SKM Group, we look at architecture from the perspective of business value. Before choosing tools, you need to understand what decisions the system must support. Do you need faster financial closing? Better customer segmentation? More accurate demand forecasts? Cleaner operational reporting? Better regulatory control?
The tool stack should follow the decision need, not the other way around.
Strong data architecture best practices help your organization reduce uncertainty and improve speed. The goal is not to build a perfect theoretical structure. The goal is to create a practical, scalable, and governable system that supports real business choices.
Standardization means your company uses shared definitions, naming rules, identifiers, and relationships across domains. Sales, finance, operations, and support should not define the same entity in conflicting ways.
This does not remove flexibility. It creates a common language.
When your teams share one model for customers, products, contracts, and transactions, reporting becomes faster and more accurate. You also reduce the cost of future integrations because new systems can connect to a known structure.
Manual checking does not scale. Automated validation should detect missing values, duplicates, format errors, broken references, unusual changes, and failed pipeline runs.
This is especially useful for executive reporting. If a dashboard refreshes every morning, your team should know whether the data is complete before leaders see it.
Automated checks improve trust because issues become visible early. They also reduce the number of emergency fixes before board meetings, investor updates, or operational reviews.
APIs are the connection tissue of modern systems. Poorly designed APIs create fragile integrations and hidden data gaps.
A scalable integration layer should use clear contracts, versioning, documentation, authentication, error handling, and monitoring. When one system changes, the rest of the ecosystem should not collapse.
This is where IT outsourcing can help if your internal team lacks capacity or specialized architecture experience. External engineering support can accelerate integration work while keeping your business focused on priorities.
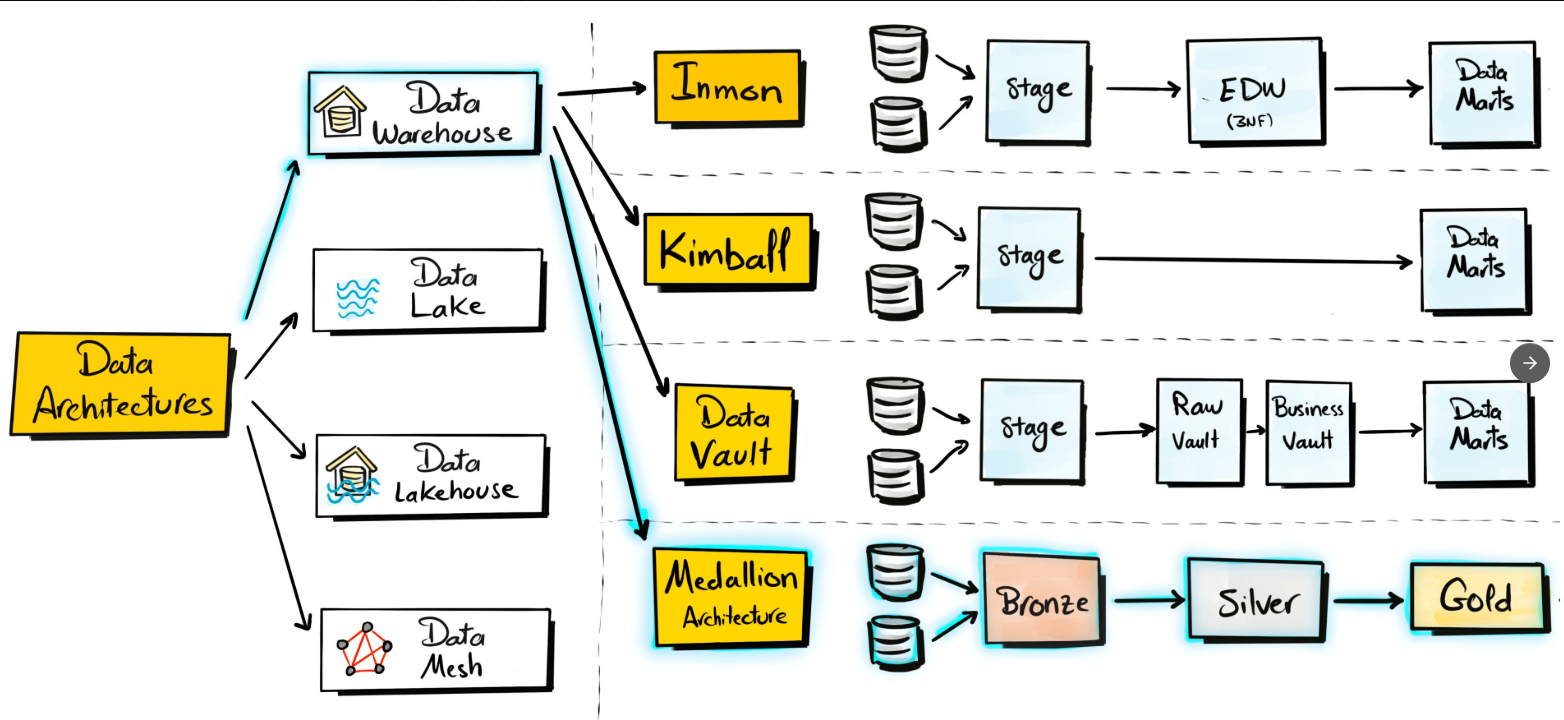
Governance does not mean bureaucracy. It means clarity.
Your company needs rules for ownership, access, quality, definitions, retention, documentation, and change management. A centralized process helps prevent local shortcuts from becoming enterprise-wide problems.
Effective governance should answer simple questions. Who owns this dataset? Who approves metric changes? Where is the definition documented? How often is the source refreshed? What happens when quality drops?
The best governance processes are practical and visible. They help teams move faster because expectations are clear.
Legacy modernization should improve data flow, not only interface design. A modernized system should expose clean APIs, separate business logic from data storage, reduce manual exports, and support scalable reporting.
Modular architecture lets your company modernize step by step. You can replace or rebuild high-risk parts without disrupting the whole organization. You can also introduce new analytics capabilities while older systems are still being phased out.
This approach works well when modernization follows the real software life cycle. Systems are not static. They evolve through planning, development, deployment, maintenance, measurement, and improvement.
A strong data architecture strategy must guide software development. Otherwise, each new application may solve one business problem while creating another data silo.
When we deliver custom software development, we treat data as a core design element. We ask how the system will create data, validate it, share it, secure it, and support reporting. This is important because custom platforms often become central business assets.
Your software should not only perform tasks. It should generate reliable knowledge.
Useful alignment usually includes:
This is also where agile methodology in outsourcing becomes valuable. Iterative delivery helps teams validate assumptions, improve data flows, and adjust architecture before technical debt becomes expensive.
Poor data architecture affects decision-making because it weakens trust. It makes reports slower, KPIs inconsistent, analytics less accurate, and executive choices harder to defend. Your company may still collect large amounts of information, but without structure, that information becomes noise.
Better architecture gives you a stronger operating base. It connects systems, standardizes definitions, improves data quality, protects access, supports traceability, and prepares your organization for automation and machine learning.
For many companies, the path forward includes legacy software modernization and custom software development. Legacy platforms must be opened, stabilized, integrated, or gradually replaced. New software must be designed with data strategy from the start.
At SKM Group, we believe data architecture is not just about technology. It is about giving you the confidence to make better decisions faster.
Check also:

Poor architecture increases decision risk. It creates inconsistent reports, duplicated work, slow analysis, weak forecasting, and lower trust in business systems. Over time, it can also increase operational costs because teams spend more effort correcting data than using it.
Executives need clear, timely, and traceable information. Bad architecture makes metrics unclear and delays reporting. It may cause leaders to approve investments, cost reductions, hiring plans, or market strategies based on incomplete or misleading data.
The most common problems include outdated databases, manual exports, missing APIs, hardcoded logic, duplicate records, unclear ownership, limited documentation, and poor integration with BI or analytics platforms.
Machine learning depends on clean, consistent, and well-labeled data. If the architecture produces duplicates, gaps, biased records, or unstable definitions, models will learn from weak inputs and generate unreliable predictions.

In our team, Dominik Bigosiński is responsible for driving the growth of online businesses through the strategic use of content. As an expert in his field, he has collaborated with organizations from the US, UK, Norway, and Poland since 2018, contributing to the development of over 100 blogs and supporting more than 450 B2B and e-commerce brands worldwide. His passion for conscious personal growth and philosophy is reflected in his work, where he focuses on delivering thoughtful, audience-centered strategies that drive long-term results.
Need tailor-made software? We build scalable, secure solutions from scratch.
Discover moreStrategic insights into technology, software development, and digital growth
Modern engineering teams are under constant pressure. They are expected to deliver faster, maintain reliable systems, operate in secure cloud environments, and achieve predictable outcomes.
Business application development is not only about writing code. It is about making the right decisions before code becomes expensive. At SKM Group, we use product roadmapping to help you turn business goals, system limits, user needs, and technology
When you invest in software, you do not pay only for features. You pay for every future change, every bug fix, every deployment, every security update, and every hour your team spends understanding the system.
When you invest in software, you are making a long-term decision that goes far beyond the initial release. The real challenge begins when your system needs to evolve—when new features are added, integrations are expanded, and existing components must
Poor data architecture does not always break your business systems at once. More often, it creates quiet damage: inconsistent reports, duplicated records, unclear KPIs, and decisions based on numbers nobody fully trusts.
Software complexity rarely appears overnight. It grows quietly with every shortcut, integration, legacy module, and undocumented business rule. At SKM Group, we see how this hidden technical weight can turn even a strong product roadmap into a slow
Your company may have many good tools. But good tools do not guarantee good communication. When business systems stop sharing data clearly, everyday work becomes slower, riskier, and harder to manage.
Every business-critical system has a second life after deployment. That life is shaped by updates, fixes, monitoring, documentation, and technical decisions that are easy to postpone.
At first, manual workflows, disconnected systems, and spreadsheets may seem manageable. But when your company begins serving more customers, processing more data, and managing more complexity, operational inefficiencies become impossible to ignore.
Modern enterprises need more than generic software subscriptions. As operations grow more complex, companies require digital infrastructure that supports automation, scalability, cybersecurity, advanced integrations, and real-time operational visibil
Modern automotive performance is no longer built only in the garage. It is built in software. Today’s vehicles rely on complex ECUs, communication protocols, telemetry systems, and real-time diagnostics that require far more than traditional mechanic
Modern companies no longer struggle with a lack of software. They struggle with too many disconnected tools, fragmented workflows, and operational processes that were never designed to work together efficiently.

If you are making decisions about modern software delivery, you will inevitably ask yourself: what is azure DevOps and why does it matter for your business? At SKM Group, we see it not as a tool, but as a structured ecosystem that connects.
When you invest in custom software, you are not just buying code—you are buying speed, reliability, and confidence. At SKM Group, we rely on DevOps tools as the backbone of that promise.
When you ask what is DevOps engineer, you are really asking about one of the most critical roles in modern software delivery. At SKM Group, we see a DevOps engineer not as a single function, but as a connector of systems, teams, and outcomes.
At SKM Group, you don’t just buy software—you invest in a process that determines whether your product succeeds or quietly fails in the background. One of the most transformative approaches shaping modern software delivery is DevOps.
You have heard the promise. Faster systems. Lower costs. Infinite scale. The cloud as a cure for every architectural weakness accumulated over twenty years of digital growth. And yet, from our experience at SKM Group, we have seen the opposite happen
At SKM Group, we meet organizations every week that still rely on infrastructure designed fifteen or twenty years ago. It runs. It supports operations. It feels stable. But beneath that surface, the architecture quietly expands your cybersecurity exp
Legacy systems rarely fail loudly. They age quietly. They grow around your organization like concrete poured decades ago – solid, load-bearing, but rigid. When documentation disappears, original developers leave, and integration requirements multiply
If you are responsible for technology decisions in your organization, you have probably heard both terms used almost interchangeably. Technical debt. Legacy systems. Obsolete platforms.
When you hear lean software development meaning, you should not think about a trendy buzzword. You should think about engineering discipline designed to remove friction from value delivery.
When you invest in software, you are not just buying code. You are buying speed, predictability, flexibility, and the ability to react to market change. At SKM Group, we see software as a living system, not a finished product frozen in time.
At SKM Group, we often see decision-makers pause at one deceptively simple question: what is a software development kit, and why does it matter so much to the success, cost, and scalability of your digital product?
From the perspective of SKM Group, when you ask what a mobile apps application really is, you are not asking a marketing question. You are asking an engineering question with direct business consequences.
At SKM Group, we see software resilience as the living backbone of modern digital ecosystems. It is the capability of your systems to absorb shocks, maintain essential functions, and recover faster than your business stakeholders expect.
As SKM Group, we often see that companies underestimate how deeply software dependency structures shape the long-term health of their digital products. You might assume dependencies “just work in the background,”
As SKM Group, we see every day how leaders like you face a rising paradox: you’re expected to innovate faster than ever, yet every new system you adopt must now prove its financial value with absolute clarity.
Technology doesn’t wait. Neither should you. Every software environment that powers your operations today will either evolve—or become obsolete. That’s the simple reality of digital transformation.
You’ve probably heard it before – “Customer is king.” But in 2025, that phrase isn’t just a cliché. It’s the operational truth that defines which businesses thrive and which fade into the noise.
Every industry, from manufacturing to finance, now depends on intelligent software products that enhance performance, streamline workflows, and enable long-term scalability.

When you think about the cloud, you probably imagine endless virtual servers humming somewhere in the background, waiting to process your business logic. But here’s the thing—you no longer have to.
Digital transformation isn’t a buzzword anymore—it’s your reality. You already know that running your business on outdated systems slows down growth, frustrates employees, and makes customers leave for competitors who can deliver faster.

When you sit down to plan your next digital product, one of the first questions that arises is: which app development frameworks will actually get you there?
The digital race is not about speed alone—it’s about precision, resilience, and the ability to deliver value faster than your competitors. As decision-makers in technology, you know the stakes are high.
When you build software, you’re not just creating a product—you’re making a promise. A promise that it will work as intended, delight its users, and deliver measurable value. But promises in software are fragile.
You’ve seen the term software scalability meaning pop up everywhere lately. But what does it really mean for your business—not just for developers? At SKM Group, we define scalability.
You know your business. You know your customers. But in today’s digital-first market, knowing isn’t enough – acting fast, adapting to trends, and delivering personalized experiences is what separates market leaders from followers
If you’re searching for ways to streamline complex builds or accelerate your software roadmap, specialized outsourcing is a smart direction. By leveraging Application Development Outsourcing or SaaS Development Outsourcing, you gain rapid access.
Your business runs on technology, whether you notice it daily or not. Choosing the right IT services shapes everything from operational resilience to your capacity for innovation.

If you're leading a business today, you're likely balancing innovation with efficiency, speed with precision, and growth with risk. That’s where specialized software outsourcing services step in — not just as a cost-saving tool, but as a strategic.

Software development processes best practices aren't just buzzwords—they are critical frameworks that shape how successful products come to life. As someone making decisions about technology investments

At SKM Group, we believe that truly successful software starts with a deep understanding of Software Engineering and Design—not just as a process, but as a discipline that brings structure
At SKM Group, we believe clarity is the cornerstone of successful software delivery. If you're navigating digital transformation or evaluating software partners, understanding what is software development methodology

For decision-makers managing IT outsourcing or legacy modernization, choosing between Agile and Waterfall is a financial and strategic decision. This guide explores how iterative implementation minimizes risk and accelerates ROI in distributed teams.
The ability to build a high-performance outsourcing development team can dramatically accelerate product delivery while reducing operational overhead. But to do it right, you need more than just a vendor
Offshore outsourcing software development has evolved from a cost-saving tactic into a strategic pillar for tech-driven organizations. When executed properly, it empowers you to scale faster, access niche expertise, and accelerate time-to-market with

Technology is the backbone of modern business. Whether you're a startup or an enterprise, your IT infrastructure determines how efficiently you operate, how well you serve customers, and how secure your data remains. Choosing the right IT service pro

The software development process is a structured approach to creating software, ensuring efficiency, quality, and alignment with user needs. It encompasses a series of stages, from gathering requirements to maintaining the final product.
Choosing the right business software development partner is one of the crucial decisions that might shape your company's future. With so many choices for enterprise software development companies, how will you go about making the right choice?
Choosing the right partner for your software project is a critical decision. Should you hire an individual custom software developer or collaborate with a full-fledged software development company?

Customized software solutions are the answer for companies that want to streamline operations, optimize workflows, and stay ahead. Here at SKM Group, we understand your need for tailored solutions that align with your unique goals.

Investing in custom software development can feel like navigating uncharted waters. As a decision-maker, you might wonder how custom software development costs against off-the-shelf alternatives, or whether it’s worth pursuing.
IT projects often run over budget or take too long. Agile changes that by delivering value quickly, adapting to evolving needs, and giving leaders control over costs and ROI, helping businesses stay competitive and responsive.

When embarking on a new software project, you're faced with a crucial question: will this idea work? You don’t want to spend months on development only to discover that a critical assumption was wrong.

If you've ever wondered how to create an app, you're not alone. Many businesses are seeking ways to expand their digital footprint, and a dedicated app can be a powerful tool to achieve just that.

Creating a mobile application is complex, and understanding the development cost is crucial for any business aiming to launch a successful app. With costs influenced by numerous variables, knowing what affects your budget and where your money goes

Having a clear, structured approach is essential. Whether you're diving into your first project or overseeing a complex, custom build, the journey can feel overwhelming.
Understanding what is a software life cycle is crucial. The term encapsulates every phase a software product goes through, from inception to retirement. At SKM Group, when you understand this life cycle deeply.

Encountering technical problems is inevitable in our tech-driven lives. This article outlines basic steps to troubleshoot common issues like internet connectivity, software bugs, and peripheral device problems.

Comments